 RankStreet
There is a lot of mysticism around AI citations. People talk about "training the model on your brand" or secret prompt tricks. The reality is more mundane and more useful: assistants that cite sources are, for the most part, running a search, reading a handful of pages and summarising them. If you understand that pipeline, you can work on each stage of it deliberately.
How to get cited by ChatGPT: understand the pipeline first
When an assistant answers a question, it draws on two layers:
- What the model already knows. Patterns learned from training data up to its knowledge cutoff. This layer shapes which brands and ideas the model is aware of, but it rarely produces a clickable citation.
- What it retrieves live. When a question needs current or specific information, ChatGPT search, Claude's web search, Perplexity and Gemini fetch results from a search index, read the top pages and cite the ones they use. This is where citations come from.
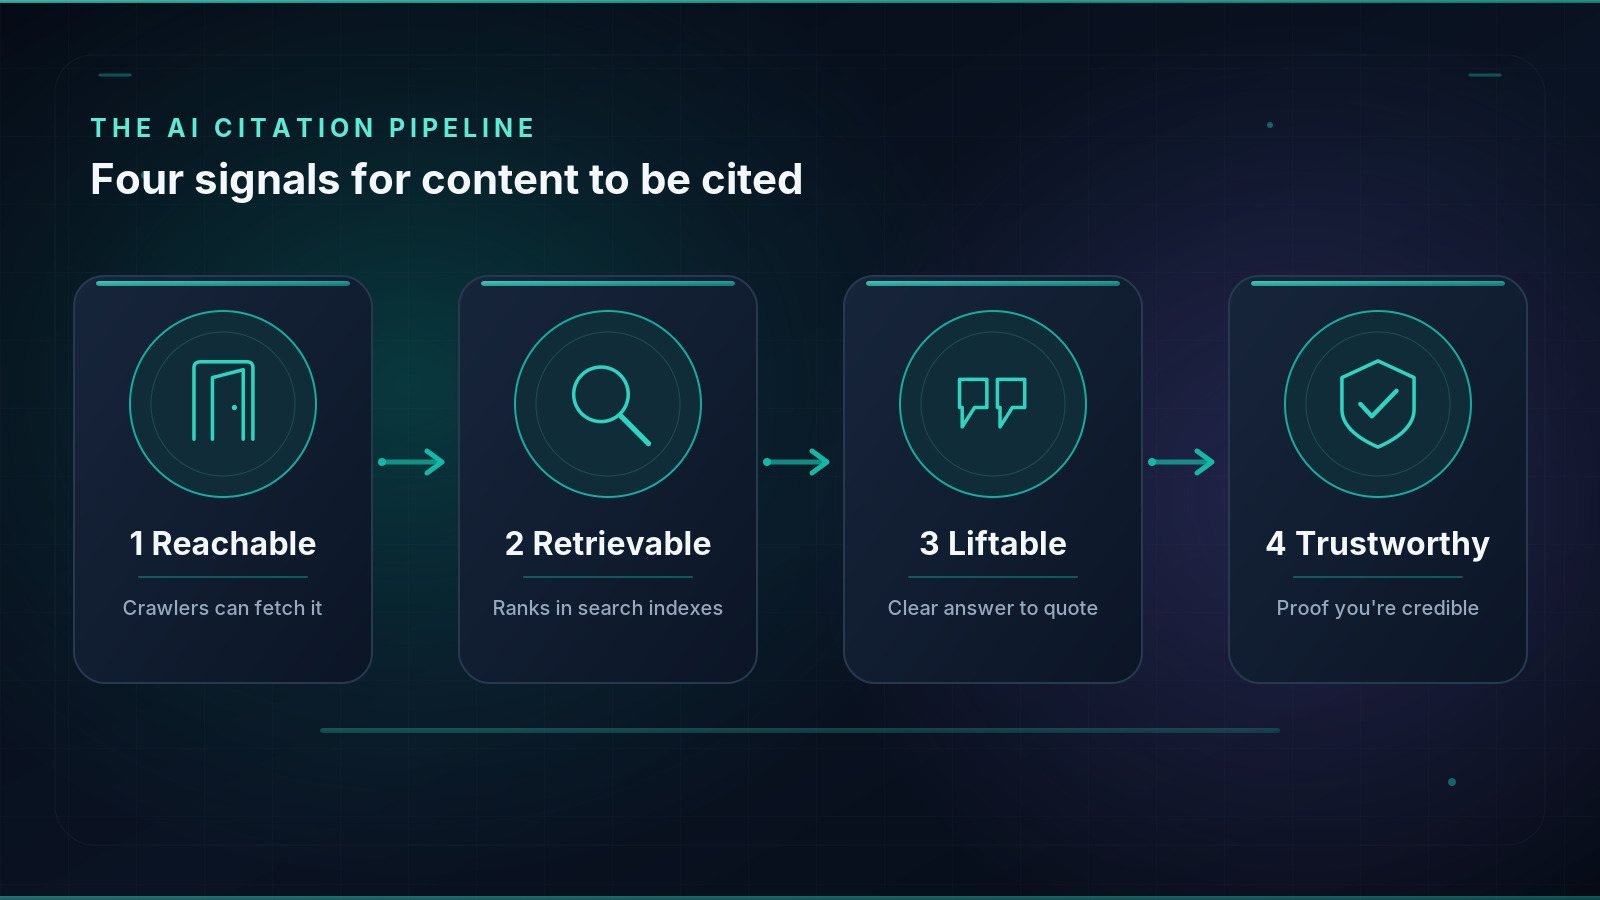
To be cited, a page has to pass four filters in order:
| Stage | Question the system is effectively asking | What you control |
|---|---|---|
| Reachable | Can my crawler fetch this page? | robots.txt, server rules, rendering |
| Retrievable | Does this page come up in search for the query? | Classic SEO, indexing in Google and Bing |
| Liftable | Is there a clean passage that answers the question? | Page structure, direct answers |
| Trustworthy | Is this source safe to attribute a claim to? | E-E-A-T, entity signals, third-party proof |
Most teams jump straight to the last row. In our audits, the first two rows are where a surprising number of sites fail.
Step 1: make sure AI crawlers can actually reach you
Each assistant uses named user agents. The ones worth knowing, according to each provider's published documentation, are:
- OpenAI:
OAI-SearchBot(for ChatGPT search results),ChatGPT-User(fetches made when a user asks),GPTBot(model training). - Anthropic:
Claude-SearchBot(search),Claude-User(user-initiated fetches),ClaudeBot(training). - Perplexity:
PerplexityBot(indexing) andPerplexity-User(user-initiated fetches). - Google: AI Overviews and AI Mode use the normal
Googlebot. The separateGoogle-Extendedtoken controls use of your content for Gemini model training, not inclusion in Search.
A common mistake is a blanket block added by a security plugin or CDN "bot fight" setting. Check your robots.txt and firewall rules. If you want to appear in AI search but prefer not to contribute to training, you can allow the search agents and disallow the training ones:
User-agent: OAI-SearchBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /
That is a business decision, not a technical requirement, and blocking training crawlers may reduce how well future models know your brand. Whatever you decide, make it deliberate. Also check that your key content renders in the HTML response; many AI fetchers do not execute heavy JavaScript the way a full browser does.
Step 2: rank in the indexes assistants search
Live retrieval runs on search indexes. ChatGPT search draws on third-party search providers, including Bing, alongside OpenAI's own crawling. Gemini and Google's AI features sit on Google's index. Perplexity runs its own index. The practical implication is simple: if you do not rank reasonably in Google and Bing for a query, you are unlikely to be retrieved for it.
Two often-skipped tasks:
- Verify your site in Bing Webmaster Tools and submit your sitemap. Many Indian sites have never done this because Bing's direct traffic is small, but Bing's index matters well beyond Bing.com.
- Fix indexing issues in Google Search Console before writing a word of new content. A page that is "Crawled, currently not indexed" cannot be cited by Google's AI features.
Step 3: write passages an assistant can lift
Once retrieved, your page competes with four or five others for the sentence the assistant writes. The page that wins usually has a self-contained passage that answers the question directly. Compare these two openings for a page targeting "what does a B2B SEO retainer include":
Before: "At our agency, we believe every brand has a story. For over a decade we have partnered with ambitious companies to unlock growth through data-driven creativity."
After: "A B2B SEO retainer typically includes a technical audit, keyword and topic research, on-page optimisation, content production, link and mention building, and monthly reporting. Most retainers run for at least six months because organic results compound over time."
The second version can be quoted almost as-is. Patterns that help:
- Answer in the first 40 to 80 words under each heading, then elaborate.
- Phrase headings as real questions ("How much does a B2B SEO retainer cost in India?") rather than labels ("Pricing").
- Use definitional sentences: "X is...", "X costs...", "X differs from Y because...".
- Prefer specifics such as ranges, steps, named standards and dates over adjectives.
- Use tables for comparisons. Assistants handle structured comparisons well and often reproduce them.
Content depth matters too. A 300-word service page rarely contains enough distinct, quotable passages to win across the range of questions buyers ask. Our own digistreetmedia.com case study is candid about this: the homepage has strong technical scores but thin main content, and that is the next fix on our list.
Step 4: give assistants reasons to trust you
Entity clarity
Assistants need to know who you are. Consistent naming, an Organization block with sameAs links to your real profiles, a clear About page and consistent details across directories all help a system connect your website to the entity it has seen elsewhere.
{
  "@context": "https://schema.org",
  "@type": "Organization",
  "name": "Example Analytics Pvt Ltd",
  "url": "https://www.example.in",
  "description": "Example Analytics builds inventory forecasting software for Indian D2C brands.",
  "sameAs": [
    "https://www.linkedin.com/company/example-analytics",
    "https://www.crunchbase.com/organization/example-analytics"
  ]
}
Authorship and freshness
Named authors with real bios, visible "Updated on" dates that reflect genuine updates, and Article markup with datePublished and dateModified all make a page easier to trust and to date. For YMYL topics, add a qualified reviewer; the fundabroad.com case study shows what that looks like.
Third-party corroboration
Assistants are more comfortable repeating a claim that several independent sources support. Mentions in trade publications, accurate listings on relevant directories and review platforms, and genuine participation in communities such as Reddit or industry forums all create that corroboration. You cannot fake this layer at scale, which is precisely why it carries weight.
Step 5: track the prompts your buyers actually use
You cannot improve what you do not measure, and AI answers vary by phrasing, location and time. Build a list of 10 to 30 prompts that reflect real buying journeys. For a B2B agency, that might be:
- "Which agencies in Delhi specialise in B2B SEO?"
- "What should a B2B SEO retainer include and what does it cost in India?"
- "Compare in-house SEO with hiring an agency for a mid-size manufacturer."
- "Who are reliable digital marketing agencies for BFSI companies in India?"
Run them regularly across ChatGPT, Claude, Perplexity and Gemini and record two things: whether your brand is mentioned, and whether your URL is cited. RankStreet's AEO/GEO tracker automates this. Save a project, add your prompts, and it re-runs them on a schedule so you can see mention rate trend over time instead of relying on one-off screenshots.
In analytics, look for referral traffic from assistant domains such as chatgpt.com and perplexity.ai. ChatGPT commonly appends utm_source=chatgpt.com to links it cites, which makes those visits easier to segment in GA4.
What changes in 2027: agents, not just answers
The trend to plan for is assistants that act as well as answer. Agentic browsing features already let assistants visit sites, compare options and fill in forms on a user's behalf. If that pattern grows, as we expect it to through 2027, your site will increasingly be "read" by software working for a buyer. That favours pages with clean HTML, clear pricing and specification information, accessible forms and structured data that states facts unambiguously. It penalises content hidden behind interactions, PDFs without text, and pricing that only appears after a sales call. Treat this as a prediction to prepare for, not a certainty, but the preparation also helps human visitors today.
What not to do
- Do not stuff brand mentions into answers. Self-promotional passages are less likely to be quoted.
- Do not gate the content that answers questions. Assistants cannot cite what sits behind a login or form.
- Do not publish fifty thin pages. Five deep, well-structured pages outperform fifty shallow ones.
- Do not neglect classic SEO. Retrieval depends on it; see SEO vs AEO vs GEO for how they fit together.
Where to start this week
- Check robots.txt and firewall rules for the AI user agents above.
- Verify the site in Bing Webmaster Tools and submit your sitemap.
- Pick three high-intent pages and rewrite the first 100 words as a direct answer.
- Add a visible FAQ with
FAQPagemarkup to each, using our FAQ schema guide. - Add 10 prompts to an AEO tracker and record a baseline.
A free RankStreet audit will show where each page stands on AEO friendliness, schema and E-E-A-T, and the AI fixes feature drafts specific rewrites for the gaps it finds. If you would rather have a senior team run the whole loop, talk to Digistreet Media.
Frequently asked questions
How do I get cited by ChatGPT?
Make sure OpenAI's search crawler can reach your pages, rank reasonably in the search indexes ChatGPT uses, open each section with a direct, quotable answer, and build trust through clear authorship, organisation details and independent mentions. Then track real prompts to see what changes.
Does blocking GPTBot stop my site appearing in ChatGPT search?
According to OpenAI's documentation, GPTBot relates to model training, while OAI-SearchBot is used for ChatGPT search. Blocking GPTBot alone should not remove you from search results, but blocking OAI-SearchBot can.
Is getting cited by Claude or Perplexity different from ChatGPT?
The principles are the same: be reachable, retrievable, liftable and trustworthy. The differences are in which crawlers and indexes each assistant uses, so check that you are not blocking any of their search agents.
How long does it take to start appearing in AI answers?
Live retrieval can pick up changes as soon as the updated page is re-crawled and ranks for the query, sometimes within weeks. Brand awareness inside a model's built-in knowledge changes far more slowly, with new model releases.
Does structured data help AI assistants cite my site?
Structured data makes facts about your organisation, authors and content explicit, which helps systems interpret a page. It is not a guarantee of citation, but combined with clear on-page answers it removes ambiguity.
Ready to put this into practice?
Run a free 60-point audit on any URL and get a prioritised fix list in under a minute.
About the publisher
Built by Digistreet Media
RankStreet is built and operated by Digistreet Media — a digital marketing and SEO agency with 13+ years across Finance, FMCG, Real Estate, B2B, Automobiles, Fashion, SaaS, Healthcare and Commerce. Prefer a senior team to run the audit and the fixes for you? Talk to Digistreet.